UX Research for AI Products

Turn your AI investment into a product people understand, trust and choose to use

Find the trust and usability issues that could slow adoption before you put your AI product in front of users.

Request AI Product Research

Trusted by Fortune 500 enterprises worldwide

Google-01 Tesla-01-1 Ebay-01-1 Adobe-01 1 Amazon-01 Cisco-01-1 Intel-01-1 Paloalto-01 BMO-01 AutoDesk-01 Walmart-01 Walt Disney-01-01-01 Anaplan-01-1 Acruex-1 FSB-1 Visa-01-1 Airbnb-01 General Electric-01 PayPal-01 Netflix-01 Twitter-01-1 Pintrest-01-1 VMWare-01 Informatica-01 Chase-01 Farmer Insurance-01 Gilead-01 PG&E-01 NBC-01 Caesars-01 Intuitive Omnissa-01 Broadcom-01 Infoblox-01-1 City National Bank-01 Servicenow-01-1 Equinix-01 Trimble-01 Lucid-01 PGE-01-1 Montefiore-01 PFU-01-1 Kaiser-01 ThermoFisher-01 Convergent-01 Chewy-01 CDW-01 Covetrus-01 Platform Science-01

What Your Team Gets

See what could stop users from trusting and adopting your AI before launch

Launch AI features users trust enough to act on

Every study ends with clear, prioritized findings that show where users lose trust, misunderstand the AI or struggle to rely on it, so your team fixes them while there is still time to act.

Ship AI that users rely on the right amount

Find out if users know when to trust the AI's answer and when to double-check it, so over-reliance and ignored outputs get caught before they cost you adoption.

Walk into product, risk and leadership reviews with evidence

Show leadership what users actually do with the AI's outputs, so your team's recommendations carry weight when decisions get made.

Get specialized AI research without another program to run

A PMO manages timelines, SLAs and delivery from start to finish, so your internal team does not take on another project to coordinate.

UX Research Engagement Models

Findings in 2 to 3 weeks, and a dedicated partner when you need one

Akraya delivers AI product research through UX research as a service (RaaS), a managed model run by one PMO with defined SLAs. We take responsibility for the research getting done, while your team keeps control of the research strategy.

Delivery Model 01

2 to 3 weeks

from your question to findings

Rapid AI research

Bring us one clear research question and we handle the rest. We scope the study, recruit the right participants, run the research and deliver findings.

Fits when: you need usability testing, pre-launch validation or an answer for a time-sensitive AI product decision.
Delivery Model 02

Ongoing

for the length of your program

Embedded AI research

Akraya manages the researcher and the program behind them, so you get dedicated research support without adding another person for your team to hire, supervise and manage.

Fits when: you need ongoing foundational, evaluative and roadmap research across an AI product.

Run both at once. One product team may need an embedded researcher while another needs a rapid study before a launch. Both run under the same PMO, so you match the model to the work without managing a different vendor for each need.

AI Products We Research

Specialists for every kind of AI your customers use

Find where your AI loses users' trust before it costs you adoption, with researchers who already know where your kind of AI breaks.

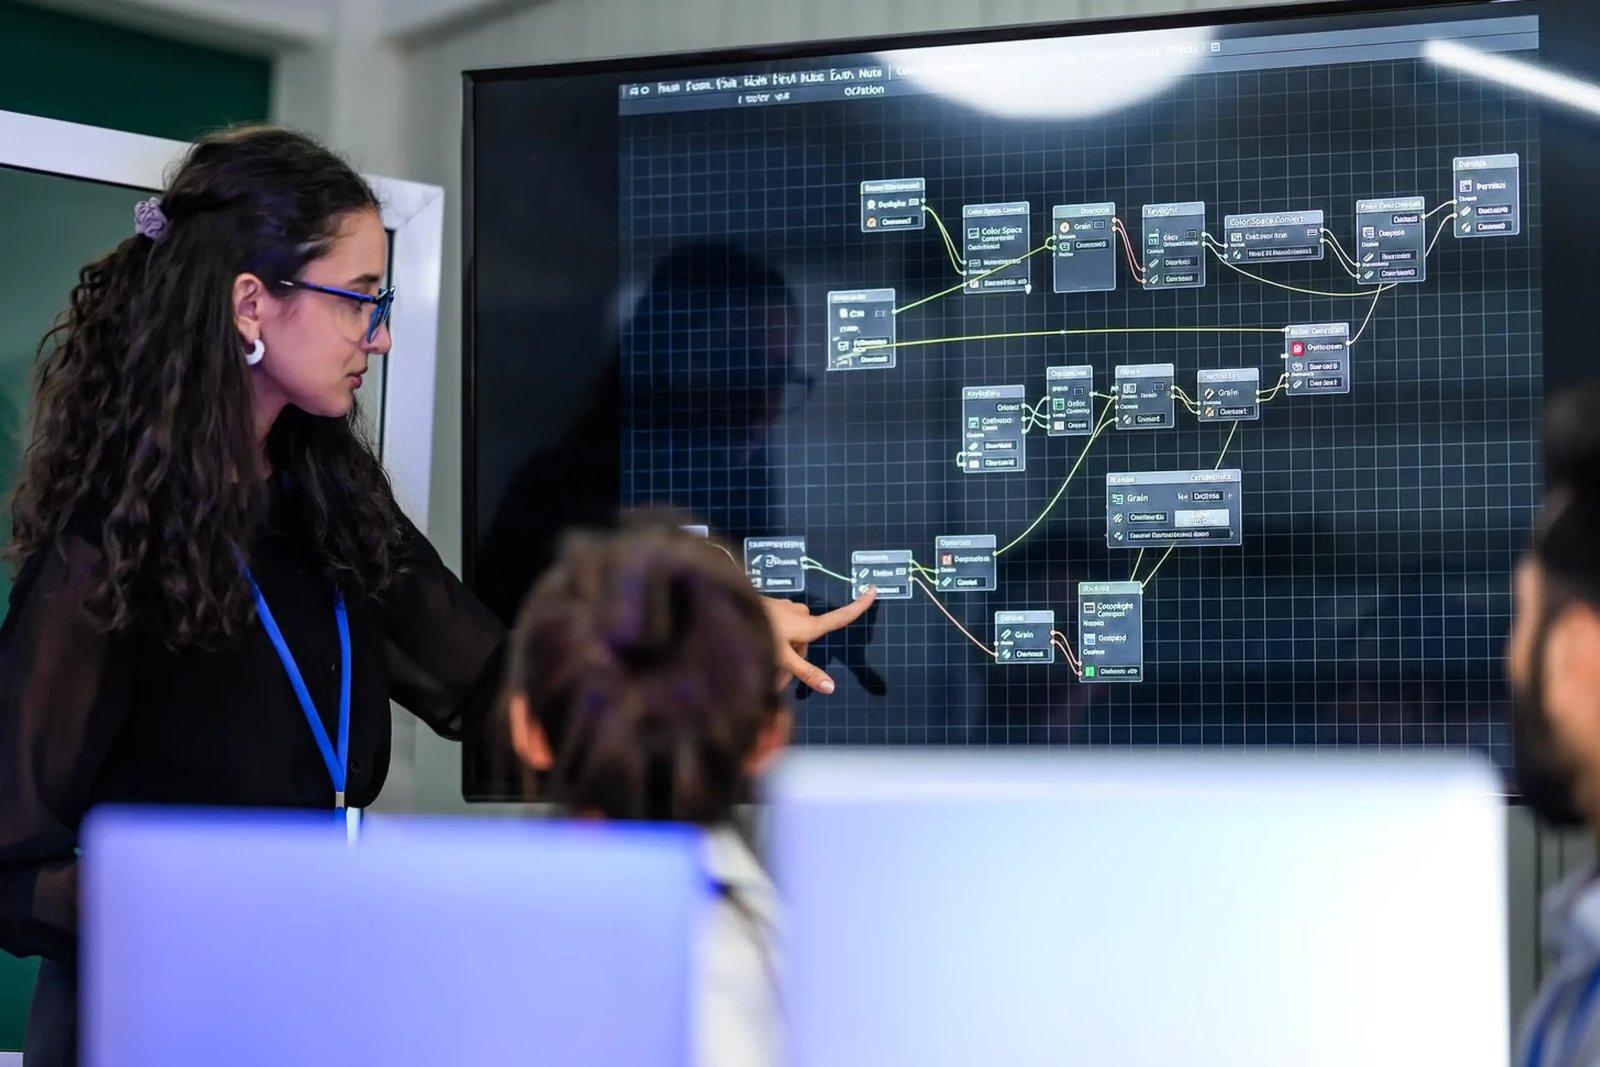
Researcher pointing at an agent workflow diagram on a large screen while colleagues watch

AI agents and agentic workflows

Test if users can follow, approve and step in on what an agent does on their behalf, so you know people can rely on it before it takes on more of the work.

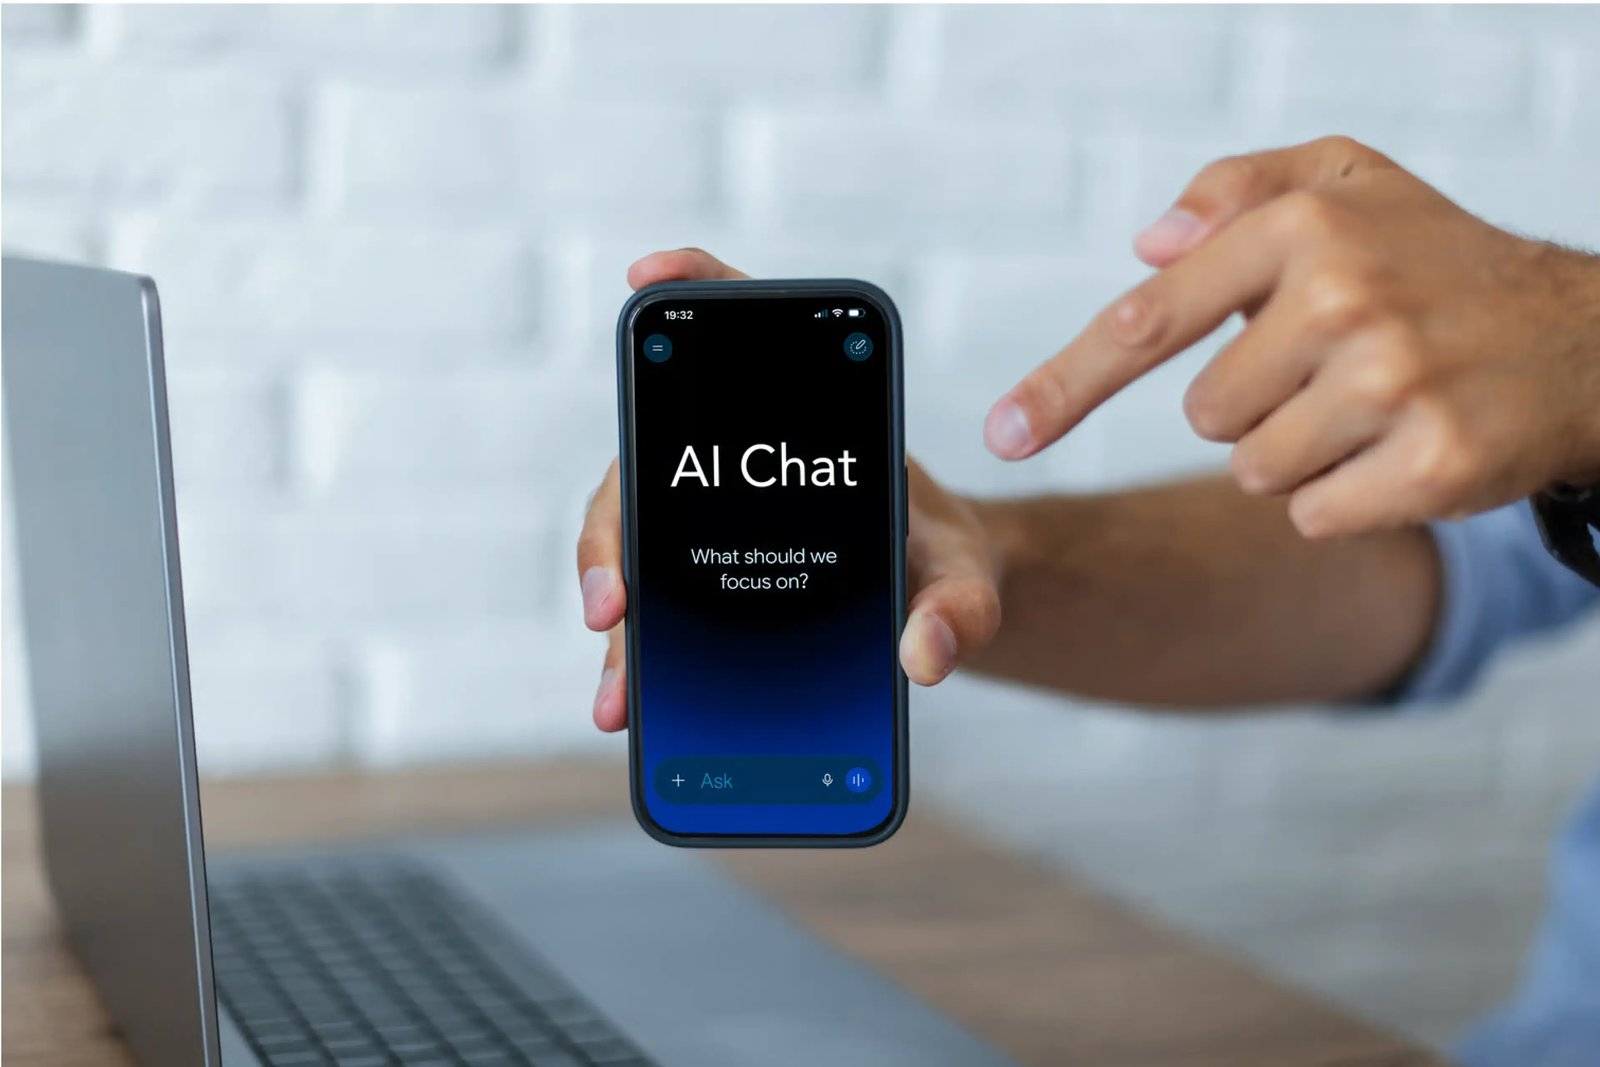
Person holding a phone with an AI chat app open while a colleague points at the screen

Chat and conversational assistants

Test how people phrase requests, read answers and react when the assistant gets something wrong, so one bad answer does not turn users away for good.

Person typing on a laptop with an AI graphic on the screen

AI features inside software and SaaS

Find out if the summaries, suggestions and assistants built into your product make it into daily workflows, so the AI features you ship become part of how people work.

Team reviewing AI output on a large display in a meeting room

AI recommendations and decision support

Test if users understand why the AI recommended something and when to question it, so good recommendations get acted on and over-reliance gets caught early.

Hand touching a glowing voice assistant microphone icon with a sound wave below it

Voice AI

Test how people give voice commands, recover from misheard requests and learn what the assistant can do, so voice features work for everyone who uses them.

Finger tapping the screen of a smartwatch

AI on wearables and devices

Test AI features on earbuds, rings, watches and other devices with small screens or none at all, where users get less feedback about what the AI is doing.

What Teams Come to Us For

The AI product decisions teams bring us in to de-risk

Each of these decisions gets more expensive to reverse once real users are relying on the AI, so this is where research pays for itself.

Before launching a new AI feature

We test how real users interpret the feature, where they get confused and how they act on the AI's outputs. You get prioritized findings while there is still time to fix the issues before launch.

When users are losing trust

We identify which outputs people doubt, ignore or override and why. That helps your team see what is actually damaging confidence and what needs to change.

Before claiming the AI is explainable

We test if users can understand how the AI reached a result, what influenced it and when they should trust or question it. That gives you evidence that explainability works outside the team that built the product.

Before expanding to new users or markets

We test across different languages, cultures, user types and edge cases to find failures that may not appear with your core participant group.

Before giving an AI agent more autonomy

For agentic products, we evaluate the decisions and actions the system takes on a user's behalf. That helps you catch incorrect, risky or confusing behavior before it reaches production.

When adoption is lower than expected

We study how people use the AI in real workflows, where they hesitate and what stops them from relying on it. You learn what needs to change for the feature to become part of how they work.

Research Capabilities and Methods

UX research that tests the AI's behavior along with the interface

An AI product can pass a usability test and still lose users after one bad answer. We use scenario testing, simulations, longitudinal studies and decision-path analysis to surface issues that may only appear across different prompts, contexts or repeated use.

Do users know when to trust the AI's answer and when to double-check it?

Trust and comprehension research

Test how users read the AI's outputs, if they can tell when the AI has given them a bad answer, and how much explanation the AI needs to give before users trust its decision.

  • Usability testing
  • Scenario testing
  • Trust research
Researcher reviewing AI model visualizations across several monitors in a library

Can users correct the AI when its answer is wrong?

Control and error recovery research

When your AI is only right 80% of the time, users need to handle the other 20%. Test if they notice wrong answers, correct or override the AI, and recognize when it is working outside what it can reliably do.

  • Scenario testing
  • Simulations
  • Usability testing
Man at a workstation with a critical error warning on his screens

Can users rely on what the agent does on their behalf?

Agentic AI research

Evaluate the outputs, recommendations and actions an agent produces, so you know if users understand what it is doing, trust it appropriately and know when to question it before you give it more autonomy.

  • Scenario testing
  • Simulations
  • Decision-path analysis
Two researchers discussing data on monitors in a dark lab

Are users over-relying on the AI and skipping their own review?

Trust and reliance measurement

Human Factors and Quantitative Psychology specialists measure how users understand, trust and rely on your AI, so you get evidence your team can use in product, risk and leadership decisions.

  • Validated behavioral measures
  • Model evaluation and measurement frameworks
Person using a chatbot on a desktop computer

Did a single hallucination make users distrust the AI from then on?

Longitudinal research

Track trust and use across repeated sessions, so you see when the AI behaves differently enough between sessions to feel unpredictable, and how one bad answer changes the way people use it.

  • Longitudinal studies
  • Scenario testing
Two researchers reviewing results on a tablet in front of an AI display

Will the AI hold up with the users it will actually reach?

Global and edge-case research

Recruit across languages, cultures, user types and edge cases, so trust, comprehension and behavior issues get caught before they show up in market.

  • Multilingual research
  • Edge-case recruiting
Woman holding a tablet in front of a glowing world map

What Akraya handles

  • Study design, or delivery of the study your UX research lead designs
  • Research on the AI's outputs, recommendations and actions, along with the interface
  • Research Ops: moderated sessions, analysis and synthesis
  • Project management through our PMO
  • Participant recruiting

What your team receives

  • Prioritized findings tied to the decision in front of you
  • Insights your product, risk and leadership teams can each act on
  • One point of contact through the PMO for the whole engagement

Have a question that is not listed here?

Every study is scoped around the decision your team needs to make. Tell us what you are trying to figure out, and our team will recommend the right approach.

Talk to our research team

Why Akraya

Specialized expertise for the parts of AI research generalist teams are not built for

Your choice holds up with leadership and procurement

Akraya runs UX research for Fortune 500 enterprises across AI products, software and wearables.

Your study is designed around how AI fails

Studies are led by AI Interaction Engineers who understand LLM limitations, model behavior and hardware constraints, including PhD-level researchers vetted against a big tech hiring bar. That helps us design research around AI-specific failure modes before they reach users.

You get evidence on trust, comprehension and reliance

Human Factors and Quantitative Psychology specialists measure how users understand, trust and rely on your AI, so your findings hold up in product, risk and leadership decisions.

Your research tests the AI's decisions along with the interface

For AI and agentic products, we evaluate the outputs, recommendations and actions the system produces, so you know if users understand what the AI is doing, trust it appropriately and know when to question it.

Your participants reflect the users your AI will actually reach

We recruit across languages, cultures, user types and edge cases, so you catch trust, comprehension and behavior issues before they show up in market.

Comparing Your Options

When AI expertise matters, the research partner you choose matters too

How building an internal team, a generalist UX research vendor and Akraya compare for AI product research
What you are weighing Build an internal team Generalist UX research vendor Akraya
Best for Ongoing research you staff and own General usability and design feedback AI-specific research tied to a launch or decision
Understanding of AI failure modes Depends on who you hire Tests AI like a standard app Researchers who understand how models break
Speed to first findings Months to open, fill and onboard a role Ramp-up plus onboarding Rapid studies return findings in 2 to 3 weeks
Participant recruiting Limited to your own panels Standard participant pools Global, diverse and edge-case recruiting
Compliance and model confidentiality Your team builds and owns it Varies by vendor Handled end to end, inside your environment
Commitment A permanent cost that is hard to flex A new contract for each project Start with a single study, with no long-term commitment, and scale from there

Akraya fits when you need AI-specific research now, want it managed end to end, and cannot spend months building the expertise, recruiting reach and research infrastructure yourself.

From Our Clients

What our clients are saying

Their responsiveness, attention to detail, and collaborative approach have made them a valued extension of our team.

eBay

Their team has demonstrated exceptional responsiveness and a genuine commitment to understanding CDW's unique requirements.

CDW PMO Team

Security, IP & Compliance

Test unreleased AI with your models and data protected

Keep sensitive model behavior inside your environment

When required, research can run inside your systems, so early model behavior, prompts, recordings and outputs stay where your team controls them.

Test unreleased AI without exposing your company

Akraya can run studies as an independent third party and keep your brand hidden from participants. That lets you test pre-launch AI features and models without signaling what you are building.

Keep consent, data handling and compliance covered

AI and privacy requirements vary by market and continue to change. We manage research consent, data handling and compliance documentation across geographies, so your team has a clear process behind every study.

Give procurement a clear engagement to approve

PMO-backed delivery, defined SLAs and a clearly defined scope make the engagement easier to evaluate as professional services. Procurement can see what is being delivered, how the work is managed and what the spend covers.

FAQ

What AI product teams ask before their first study

Yes. For agents, we test the decisions and actions the AI takes on a user's behalf, using scenario and simulation testing and decision-path analysis. You learn if users can rely on what the agent does for them.

Research can run inside your systems and as an independent third party. Sensitive model behavior, prompts, recordings and findings stay in your environment, and we can run studies without revealing your company to participants.

Both meet in the work. We evaluate how real users understand and act on what the model produces, and we can support model evaluation and measurement frameworks alongside usability and trust research.

Participant recruiting is part of the engagement, including diverse, multilingual and edge-case users your AI will reach. That is how failures tied to culture, language or unusual inputs show up before launch instead of after.

Our Human Factors and Quantitative Psychology specialists use validated behavioral measures, so trust, comprehension and reliance are captured with evidence you can defend in product, risk and leadership reviews.

We can scope and begin in days. Rapid studies return findings in 2 to 3 weeks. Timelines depend on the study design and how hard participants are to recruit, and your scoped proposal includes the full timeline.

We run the research as a managed service, so execution sits with us. You bring the question and the access your researcher needs, and we handle scoping, participant recruiting, fieldwork, analysis and the readout. Akraya also manages and supervises the researchers, so bringing us in does not become another program for your team to run. See how UX research as a service works.

We price research per engagement, scoped to the work delivered rather than by headcount, so what you pay maps to the research and the decisions it supports. Cost depends on the model and the scope: a single rapid study is scoped on its own, while embedded engagements are ongoing and sized to how much research your teams need. You can start with one study, with no long-term commitment, and expand from there.

We manage consent, data handling and compliance documentation across regions, and adjust as privacy and AI rules shift, so your team does not carry that work.

That is often the best time. Testing before launch means you find where the AI loses trust or breaks while you can still change it, and we can run confidential studies so nothing leaks before you are ready.

Find out what could stop users from trusting your AI

Tell us what you are building and which decision is coming up. We will recommend the right study, model and timeline.

  1. Intro call

    We learn about your AI product, your users and the decision coming up.

  2. Scoped proposal

    You get a recommended study plan, model and timeline.

  3. We start

    Your researchers start the study and report to your team.

Start with a single study, with no long-term commitment.

How can we help you today?